This explainer unpacks the hidden data pipelines of generative AI, revealing why standard public chat tools are prone to leaking enterprise data. It details vulnerabilities like permanent memory banks and prompt injection, then presents enterprise-grade solutions using cryptographic isolation and compliance with regulations like GDPR and the EU AI Act.
This video plays from YouTube, which can set cookies on your device.
Generative AI transforms raw text into numerical vectors, fundamentally fusing private context into the model's training parameters, making data difficult to separate once blended.
Public chat tools are vulnerable to data leaks through unencrypted log buffers, indirect prompt injection, multi-tenant failures, and server-side request forgery (SSRF).
Enterprise solutions like Adamero use cryptographic isolation, field encryption, and secure hosting to prevent data leaks and ensure compliance with strict regulations.
European compliance frameworks like GDPR and the EU AI Act emphasize transparency and data control, with features like the right to be forgotten and human-in-the-loop exemptions.
Effective AI security requires not only strong platform architecture but also proper human operational habits, including staff training and diligent management of credentials and permissions.
Welcome to this explainer. Let's just jump right in. Today we're unpacking the anatomy of an AI data leak. We are going to peel back that friendly conversational interface of generative AI to look at the hidden data pipelines running underneath. And more importantly, we're going to figure out exactly why standard public chat tools are just so notoriously prone to leaking enterprise data. To kick things off, picture this, and it's a pretty relatable dilemma. It's 8:15 a.m. A
product manager sits down at her desk. She's got a draft of next quarter's strategic road map, a table of completely unannounced pricing changes, and some raw notes from a highly private customer interview. She just needs a quick summary, right? So, she copies the whole block of text, past it into a standard public web chat tool, and boom, gets her answer in 4 seconds flat. But here is the absolutely crucial question. What actually happens to that confidential text when she hits send and closes her browser tab? Where does it
go? Okay, let's dive into this. To really understand the risk here, we have to look at how data is fundamentally stored. Now, traditional SQL databases, they are highly structured. They store data in explicit rows and columns, and they only pull up a record if you query the exact matching key. It's basically like a highly organized, locked filing cabinet. But generative AI, it completely changes the game. It takes your raw text and transforms it into highdimensional numerical vectors. It
fundamentally fuses your private context directly into the model's background training parameters. So, it's less like a filing cabinet and way more like mixing paint. Once those colors are blended together, it is incredibly hard to separate them back out. And when you look at the standard public chat pipeline, you immediately see why this is such a massive problem. Your data doesn't just travel from your laptop to a locked box. No, it goes from your initial user prompt, sits in web interface logs, travels across network perimeters, often hopping through
completely unmonitored third party middleware before finally landing in the vendor's model retainment nodes. In a multi-enant environment, your proprietary data is suddenly taking this very public, messy, multi-stop road trip across the cloud. Which brings us to section one, our first major vulnerability known as the permanent memory bank. See, raw prompts are often captured in unencrypted log buffers so human annotators can review them for fine-tuning. Because of this, your data gets permanently encoded into the model's actual parameter weights. And
once information enters those weights, removing it is basically impossible without completely rebuilding a multi-million dollar AI system from scratch. So without an enterprise contract that strictly guarantee zero data retention, fragments of that top secret pricing table from our product manager could easily reappear months later served up in a chat answer to a completely different user sitting halfway across the world. No way you want that, right? And unfortunately the leaks don't stop there. Let's move to section two. Indirect prompt injection
and multi-tenant failures. Clever users can actually craft adversarial prompts that trick the AI into ignoring its safety rules and just spilling confidential background instructions. Plus, shared database indexes can accidentally cross wires, leaking private data like executive salaries simply because the topics shared a tight semantic similarity. It's crazy. And because these AI tools often browse the live web, they are super vulnerable to
serverside request forgery or SSRF. Essentially, an attacker tricks a gullible unvetted server into visiting private network addresses. Without strict guardrails, feeding the AI a local address like 127.0.0.1 allows an attacker to map out your internal network topology and literally steal local credentials. So what is the fix here? Enter section 3, the enterprise fortress and the absolute power of cryptographic
isolation. We are talking about building security directly into the application core. Let's look at how a platform like Adamero engineers this from the ground up so your market intelligence never compromises your proprietary data. Contrast that messy public pipeline we just talked about with this pristine four-step enterprise architecture. Your prompt goes straight to an inprocess engine. Zero middleware hops. It then under goes field encryption before being securely tucked away in an isolated vector vault in Germany. Every single
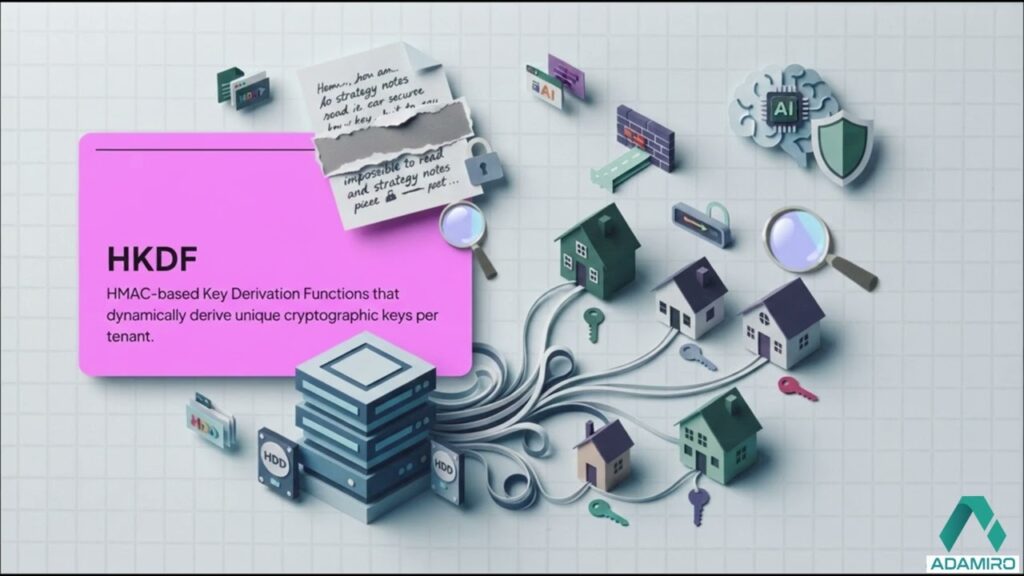
connection is locked down over TLS 1.2 plus encryption connecting strictly to managed endpoints with rockolid zero training contracts. Now what's really interesting here is the HKDF field encryption. HKDF stands for HMACbased extract and expand key derivation functions. I know it's a mouthful, but in plain terms, it means Adamiandro dynamically deres unique cryptographic keys for every single tenant. They aren't just encrypting the hard drive.
They are encrypting the specific database columns holding your data using a key tied to your unique account. So even if a bad actor somehow managed to steal an offline database stomp, your strategy notes would be mathematically impossible to read. And it goes a step further with something called secret box payload encryption. In a vector database, you have the mathematical numbers used for searching and then you have the raw text snippets that actually get shown back to the user. Admir uses symmetric secret box encryption on all
those free form context fields before they ever hit the database. The only things left unencrypted are the mathematical floatingoint vectors which are totally meaningless on their own. The raw text completely locked down. Geographically, this entire setup respects sovereign European hosting boundaries. The application core sits in Sweden while those isolated vector memory vaults are kept safely in Germany. Your data literally never leaves European jurisdiction. And remember that SSRF web fetching attack
we discussed earlier. This architecture uses strict outbound network filters that automatically validate every HTTP redirect and actively block any requests trying to hit private or loop back IP addresses, which perfectly sets up section 4, aligning natively with European compliance, specifically the GDPR and the EU AI act. Under these rigorous frameworks, transparency is everything. The platform acts as a dedicated data processor for your notes,
naturally supporting requirements like the right to be forgotten. While AI generated images carry IPC metadata and AI text usually requires public disclosure, there's a really fascinating nuance to the EU AI act. The human in the loop exemption at Amiotra, whether copy was autolabeled or reviewed by a named human editor who assumes legal responsibility for the final text. If a human editor signs off, the platform documents it, granting an explicit exemption from those AI labeling
requirements. You stay fully compliant, completely headache-free. But hey, compliance also means control, right? Look at these self-service eraser retention windows. 30, 90, 180, and 365 days. You actually hold the keys to your data. You don't have to file some tedious support ticket and wait weeks for a vendor to purge your information. You get instant deletion straight from your dashboard. A daily cleanup job runs and ensures your data life cycle is entirely on your terms. Still, the
strongest fortress in the world won't save you if someone props the front door wide open. So, let's look at section 5, fixing operational AI risks. Strong platform architecture absolutely has to be paired with proper human operational habits. This risk matrix lays it out brilliantly. To stop raw credential pasting, we have to train staff to use sanitized placeholders instead of real API keys. To fight malicious web context attacks, yes, we rely on the inprocess network filters, but we also train
editors to actively inspect source summaries. We need to stay on top of stale channel tokens to prevent publishing failures and tightly manage seat caps so we don't end up with overallocated permissions. Technology enables security, but human habit sustains it. Which brings us to our final thought for this explainer. I want you to think back on your own workflow this week. Think about the notes, the data, the half-finish ideas you fed into various web tools. Ask yourself, who actually owns the confidential text you
pasted into your browser today? By understanding the anatomy of an AI data leak and demanding enterprisegrade cryptographic isolation, you can make absolutely sure that the answer to that question is always you do. Thanks so much for diving into this with me. Stay curious.
We use a small number of cookies to run this site and, if you allow it, to understand how it is used. Learn more
Cookie preferences
Strictly necessary
Required for the site to work. Cannot be turned off.
Cookies in this category (12)
Name
Provider
Purpose
Duration
adamiro_consent
Adamiro
Stores your cookie preferences.
12 months
wordpress_logged_in_*
Adamiro (WordPress)
Keeps you signed in. Only set once you log in.
Session
wordpress_sec_*
Adamiro (WordPress)
Secures your authenticated session on HTTPS.
Session
wp-settings-*
Adamiro (WordPress)
Remembers your admin/dashboard interface preferences.
1 year
adm_2fa_trust
Adamiro
Remembers a trusted device so two-factor login isn\'t required every time.
Up to 30 days
adm_fr_runs
Adamiro
Counts how many times this browser has used the free First Round board, so the free tool cannot be run without limit. Holds a count and a date, never your input.
7 days
adm_slt_runs
Adamiro
Counts how many times this browser has used the free Sounds Like Them test, so the free tool cannot be run without limit. Holds a count and a date, never your input.
7 days
__stripe_mid
Stripe
Fraud prevention for card payments. Set by Stripe while a card form is open, on checkout and on the page where a new account owner adds their card.
1 year
__stripe_sid
Stripe
Fraud prevention for card payments. Stripe\'s short-lived session marker while a card form is open.
30 minutes
adamiro_dl
Adamiro
Remembers that you confirmed your Adamiro Signals subscription, so downloads open without signing up again. Only set once you confirm.
12 months
adamiro_currency
Adamiro
Remembers the currency you chose for prices. Only set when you pick one.
12 months
adm_oauth_bind
Adamiro
Makes sure a social-account connection you start is completed in the same browser, so nobody else can attach their account to yours. Only set while you connect an account in Reach, and removed when the connection finishes.
10 minutes
Analytics
Helps us understand aggregate site usage. Off by default.
Cookies in this category (2)
Name
Provider
Purpose
Duration
_ga
Google Analytics (via Site Kit)
Distinguishes visitors for aggregate traffic measurement.
13 months
_ga_*
Google Analytics (via Site Kit)
Persists GA4 session state for this property.
13 months
Marketing
Used to measure and personalize marketing.
Cookies in this category (2)
Name
Provider
Purpose
Duration
VISITOR_INFO1_LIVE
YouTube (Google)
Set by YouTube when you play a video, to estimate bandwidth and remember player settings.
6 months
YSC
YouTube (Google)
Set by YouTube when you play a video, to tell playback sessions apart.